Making Claude Code run its own review: two days of hooks
Introduction⌗
You ask Claude Code to review its own code before every commit. It skips the review anyway, and says the diff was small.
I have a rule in my global instructions that says production code goes through a simplification review before it is committed. The review is a Claude Code skill that looks for code that can be deleted: reinvented standard library, abstractions nobody asked for, comments that repeat the code. The rule was there, the skill was there, and the agents still walked past both.
Anthropic’s advice for this is clear: if Claude keeps missing a line in CLAUDE.md, turn it into a hook. A hook is a script Claude Code runs at a fixed point, for example before a tool call, and it can block that call. So I built one. Then I built it again, because the first one watched the wrong thing. Then the second one broke twice on the day it went live, and I had to skip my own review to get a push out.
This post goes through those two days in the order they happened, because every setback changed the design.
Side Note: This is my personal setup, in ~/.claude, not something the team runs yet. Times are Oslo time.
How often it happened⌗
Before building anything, I wanted to know if this was a real problem or a feeling. So I went through my session transcripts since late October and looked for the places where an agent admitted it had skipped a step: “I skipped”, “I should have”, “I did not run”.
There were 794 matches. After reading them, 123 were real admissions. They fell into groups:
- Claims of “verified” with nothing run behind them: 19
- Steps of the testing skills skipped: 19
- Asking me something before reading the code that answers it: 13
- Delegation rules ignored: 9
- PR steps skipped: 8
- The simplification review skipped before a commit: 7
The last group was the one I wanted, because the reason was the same every time: the diff was small. And unlike “verified”, it is something a script can see. Either the skill ran or it did not.
Where a hook can step in⌗
Before the build, it helps to know what a hook can see, because everything below depends on it.
Claude Code does almost everything through tools. Editing a file is a call to the Edit tool, running a command is a call to the Bash tool, and loading a skill is a call to a tool named Skill. A hook is tied to an event around those calls, and a matcher picks which tool it cares about:
| Event | When it fires | What the hook can do |
|---|---|---|
PreToolUse |
Before the tool runs, with the full input, for example the shell command | Block the call. Claude sees the hook’s message and has to deal with it |
PostToolUse |
After the tool has run | Record what happened. The call is already done, so it can’t be stopped |
So when the agent loads the review skill, that is a Skill call with the skill’s name in it, and a hook can catch it. When the agent runs git commit or gh pr create, that is a Bash call with the command in it, and a hook can read the command and block it.
Git has hooks of its own, and they are a different thing. A pre-commit or pre-push script runs inside git, whoever started the command: Claude, a script, or me in my own terminal.
Every hook also gets the path to the session transcript. Claude Code writes each message and tool call to that file as it happens, so a hook can look back at what the agent has done so far.
Day one: a commit gate that reads the transcript⌗
The first version was two PreToolUse hooks on the Bash tool, so both read every shell command before it ran:
- A commit gate that blocked
git commitwhen production files were staged, until the simplification review had run after the last production edit. - A PR gate that blocked
gh pr createandgh pr readyuntil the code-review skill had run after the last production edit. A draft PR stays allowed, because that is where the plan lives and the review comes before ready.
To know what “after the last production edit” means, both hooks read the session transcript. They look for the last Edit or Write call on a production file and the last Skill call that loaded the review, and compare the timestamps. They also read the transcripts of subagents, because a lot of edits happen there.
Production means code that ships. Tests, docs and lock files don’t count. Dependency manifests like package.json, pom.xml or go.mod do count.
I also wanted a way out for myself. Some work is a spike, and I don’t want a review on a throwaway branch. So my message starting with skip review lets the gate through once, and every skip goes into a log.
Three things went wrong on the first day.
The skip phrase fired by itself. I wrote a message that had “skip review” somewhere in the middle of a sentence, and the gate let the next commit through. Now it only counts when the message starts with it.
Loading the skill was not the same as doing the review. The Skill call only puts the skill’s instructions in front of the agent. Nothing in it says the agent then followed them. A PR passed the gate where the agent had loaded the review skill and then gone straight on to gh pr create. The Skill call was in the transcript, so the gate was happy. So I added a second condition: after the skill loads, the agent has to write the review result in its reply, where the hook can find it in the transcript. For the simplification review that is a line like “Lean already. Ship.”, for the code review a verdict.
The PR gate only saw the obvious commands. gh pr create is one way to open a PR. gh api with the right endpoint is another, and so is curl. The gate learned to catch those too, and to read cd other-repo && gh pr create as a PR in the other repo.
At the end of day one, the tests passed, the gates blocked what I asked them to block, and I thought it was done.
Day two: the agents were not ignoring the hook⌗
The next day I was still seeing reviews skipped. My first thought was that the agents were just ignoring the hook. Anthropic says hooks give consistency, but an agent that walks around a hook doesn’t solve anything.
Then I went through one of the sessions properly. It was a large change, done by an orchestrator agent with a few subagents:
- One agent rewrote a Kotlin file with a Python script, run through the shell. But the gate only counted
EditandWritetool calls as edits. This was aBashcall runningpython3, so to the gate no production file had changed. - The subagents worked in their own git worktrees and edited files through the shell too. Again these were
Bashcalls, so as far as the gate could tell, nothing had been edited. - Their commits came back to the main branch with
git cherry-pick. But the gate only stepped in on aBashcall withgit commitin it. A cherry-pick makes a commit without that command, so the gate never ran.
Two commits went in with no review, and the hook didn’t see either of them.
The agents were not ignoring the hook. The hook was watching the action, which tool made the edit, and there are too many ways to change a file. And it blocked at commit, which is one of several ways code gets into a branch.
Picking the hook type and the stage⌗
That is when I stopped and thought about it differently. Hooks can help, but you have to think clearly about which type of hook, and at which stage.
What I settled on:
- Check the result, not the action. What matters is the content of the files that leave the laptop. It doesn’t matter if they changed through
Edit, a Python script,sed, a cherry-pick or a merge. - Block at the step every route passes through. Commits can come from many places. Code leaves the laptop through
git push, and a PR becomes reviewable throughgh pr createorgh pr ready. Those are the places to block. - Use each hook type for what it is good at. A
PostToolUsehook runs after a tool call and can record what happened. APreToolUsehook or a git hook runs before something and can stop it.
I also had two limits I gave myself: the solution should be simple, and it shouldn’t cost speed or tokens.
The fingerprint gate⌗
The new setup has three parts.
1. When the review runs, save a fingerprint. A PostToolUse hook with the matcher Skill fires right after the agent loads the review skill. It finds every git repo and worktree the session has touched and saves the git blob hash of each changed production file. That hash is what git hash-object gives you: change one byte and it changes. The record goes to a small JSON file outside the repo.
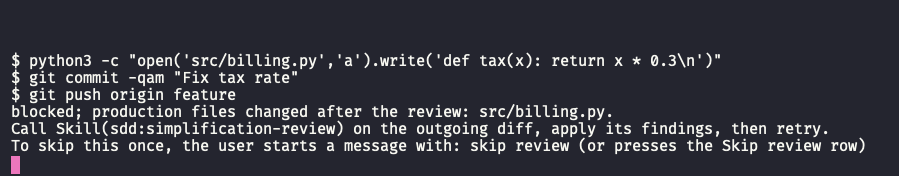
2. Before a push, compare. This one is a git hook, not a Claude Code hook, so it runs on every push from the agent’s shell, whichever way the commits were made. The pre-push hook takes the files in the outgoing commits and hashes them. If every file matches a saved fingerprint, the push goes through. If one doesn’t, the push stops and says which file changed after the review:
In that screenshot the review ran, then a Python one-liner changed src/billing.py, the change was committed, and the push stopped. The gate doesn’t know or care that it was Python.
3. Before a PR goes up for review, the same check. The PR gate from day one stays as a PreToolUse hook, but it now compares the branch against the code-review fingerprint instead of reading timestamps.
Two details made this work the way I wanted.
Only agent shells are gated. Git reads core.hooksPath from config, and config can come from environment variables: GIT_CONFIG_COUNT, GIT_CONFIG_KEY_0 and GIT_CONFIG_VALUE_0. I set those in the env block of Claude Code’s settings.json, so every shell Claude starts uses my hooks folder. My own terminal doesn’t have them, so when I push by hand nothing is checked. The hooks folder has a small shim for each git hook name, so a repo’s own hooks still run after mine.
The agent can’t switch it off easily. A second PreToolUse hook blocks git push --no-verify, a push that sets its own core.hooksPath, and any command that touches the folder where the fingerprints live. A deny rule in the settings stops the edit tool from writing there too.
The skip still exists, with two changes. It lasts 15 minutes from my message, and one skip lets through one push and one PR, not everything after it.
The commit gate from day one is gone. I deleted it with its tests, because the push gate covers everything it did, and more.
It doesn’t cost any tokens. The hooks are shell and Python scripts, and Claude only sees them when a push is blocked.
It broke twice on the first day⌗
I wired the new gate into my settings and went back to work. The same day it blocked a push it should have let through. Twice.
The first time, the review was done and the push said the files had changed. The session was long, and the transcript had 1,938 lines with a working directory on them, from only 30 different folders. The fingerprint hook asked git for the repo root once per line. That took 11.4 seconds. The hook has a 10 second timeout in my settings, so Claude Code stopped it and no fingerprint was saved at all. To the push gate, it looked like the files had changed after a review that never happened. The fix was to drop the duplicate folders before calling git, which brought it down to 0.1 seconds. There is a test for exactly that now, with a long transcript.
The second time, the agent did the review and the gate didn’t believe it. Remember the rule from day one, that the agent has to write its result after the review? The agent did the review, but wrote its result only in its thinking. The transcript keeps thinking blocks empty, so the gate found no result and blocked the push. I was in the middle of a PR, the agent was stuck, and I typed skip review to get it out.
The fix was to delete that rule from both gates. Once the gate compares file contents, the result text adds nothing. The fingerprint already says the review skill loaded on exactly these files. And an agent that wanted to fake it could just type “Lean already. Ship.” anyway.
What it still doesn’t catch⌗
A few things I know about and have left as they are:
- When I load the review skill myself with a slash command, no fingerprint is saved, because the hook watches the
Skilltool, not my typing. - A fingerprint written by hand into the folder would pass. The guard makes that hard for the agent, not impossible.
- The guard blocks any command that mentions a push together with
--no-verify, so a commit message with “push” in it gets blocked too. - Whether a review was good is a different question. The gate only knows it ran on this code.
Conclusion⌗
Two days and three versions. What runs now is about 1,000 lines of shell and Python, plus the tests.
The first version failed because it watched how files changed, and agents have more ways to change a file than I had thought of. The second one failed in production because of a timeout I hadn’t tested for, and a rule that read the agent’s words instead of the code. What is left checks the files that leave the laptop, at the moment they leave.
In about a week I will count the skips and the admissions again, and decide whether this moves into the plugin the team uses.